Think Google “sees” your website the way you do in a browser? It doesn’t. That myth trips up more site owners than any algorithm update I’ve dealt with in 15 years of doing this.
Understanding how search engine crawlers work changes how you build, structure, and troubleshoot a site. Once you get what Googlebot actually does, crawl budget waste and indexing headaches start making a lot more sense.
What A Crawler Actually Does When It Visits Your Site
A crawler is a bot, not a browser tab with eyes attached. Googlebot requests a URL, downloads the raw HTML response, then queues that page for rendering later. That two-step process trips up a lot of JavaScript-heavy sites.
Here’s the sequence I explain to every new client: the crawler fetches the HTML, checks `robots.txt` for permission, reads meta directives like `noindex`, then hands the page to a rendering queue. That rendering step can lag the initial crawl by minutes or in some cases 2-3 days on large sites with tight crawl budgets.
The crawler also logs response codes. A `200 OK` gets processed normally. A `301` redirect passes the crawler to a new URL and usually gets followed within the same session. A `404` or `410` tells the bot to drop that URL from future consideration. I’ve seen sites lose 18% of indexed pages in a single month because a migration threw thousands of unexpected 404s.
Speed matters here too. Google’s crawl infrastructure adjusts fetch rate based on how fast your server responds. If your Time to First Byte (TTFB) creeps past 600ms consistently, crawlers slow down to avoid overloading you. That’s not punishment, it’s just throttling, but it still means fewer pages get visited per day.
The Journey From Discovery To Index
Crawling and indexing are two separate jobs, and conflating them is the second-biggest myth I run into. Discovery happens first. Indexing happens after, sometimes much later.
Google discovers new URLs through a handful of channels: your XML sitemap, internal links, external backlinks, and RSS/Atom feeds it already trusts. A submitted sitemap in Google Search Console doesn’t guarantee a crawl. It just adds the URL to a priority queue.
Once fetched, the page goes through parsing. Googlebot extracts links, reads structured data, and evaluates content signals before deciding whether the URL deserves an index entry at all. Thin or duplicate pages often get crawled but never indexed. I checked a client’s coverage report last quarter and found 4,200 crawled URLs sitting in “Crawled – currently not indexed” for over 60 days, mostly thin tag archive pages nobody needed.
Indexing itself involves tokenizing content, generating embeddings for semantic matching, and storing the page in Google’s index alongside hundreds of ranking signals. This isn’t instant. A brand-new domain might wait 1-2 weeks for first indexing, while an established site with strong crawl history can see new pages indexed within hours.
Crawl Budget: Why Not Every Page Gets Visited Equally
Crawl budget is the number of URLs a search engine is willing and able to crawl on your site within a given timeframe. Big sites feel this. Small ones rarely do.
Two factors set your budget: crawl rate limit (how much your server can handle without breaking) and crawl demand (how much Google actually wants your pages). A site with 500 pages and solid authority rarely hits a ceiling. A site with 2 million product pages absolutely does.
Here are five things that quietly drain crawl budget on larger sites:
- Faceted navigation generating thousands of near-duplicate URL parameters.
- Redirect chains longer than 2 hops, which waste fetch requests on dead ends.
- Server response times averaging above 1 second under bot load.
- Orphaned pages with no internal links, forcing reliance on sitemap-only discovery.
- Soft 404s, where a page returns `200 OK` but shows “no results found” or empty content.
I worked with an e-commerce client running 340,000 SKUs. Faceted filters alone created 1.1 million crawlable URL combinations. We blocked parameter combinations in `robots.txt` and consolidated with canonical tags. Crawl requests to useful pages jumped 40% within six weeks, based on Search Console’s crawl stats report.
Reading Crawl Stats And Server Logs Like A Pro
Search Console’s Crawl Stats report is the first place I look when a client says “our new pages aren’t showing up.” It breaks down requests by response code, file type, and purpose (discovery vs. refresh).
Server log analysis goes deeper though. Tools like Screaming Frog Log File Analyser or the log module in JetOctopus let you see exactly which bot hit which URL, when, and what status code came back. This is the only way to confirm Googlebot is actually visiting your priority pages, not just guessing from aggregate charts.
A quick question-and-answer on the stuff that confuses people most:
Does a high crawl count mean good SEO? Not necessarily. I’ve seen sites with 50,000 daily crawl hits and mediocre rankings because most of that budget went to junk URLs.
Should I worry if Googlebot hasn’t visited a page in 30 days? Depends on the page. A cornerstone article should get recrawled every 1-2 weeks. A static “shipping policy” page recrawled every 45 days is fine.
Can I request a crawl manually? Yes, through the URL Inspection tool in Search Console. It’s rate-limited though, capped around 10-12 requests per property daily last I checked.
Log file review usually surfaces one surprise per audit. On one project, 22% of all crawl hits were going to expired promotional URLs from two years back. Nobody had cleaned up the redirects.
Technical Signals That Guide Or Block Crawler Behavior
Crawlers respond to explicit signals more than guesswork. Get these wrong and you either block valuable pages or waste budget on ones that don’t matter.
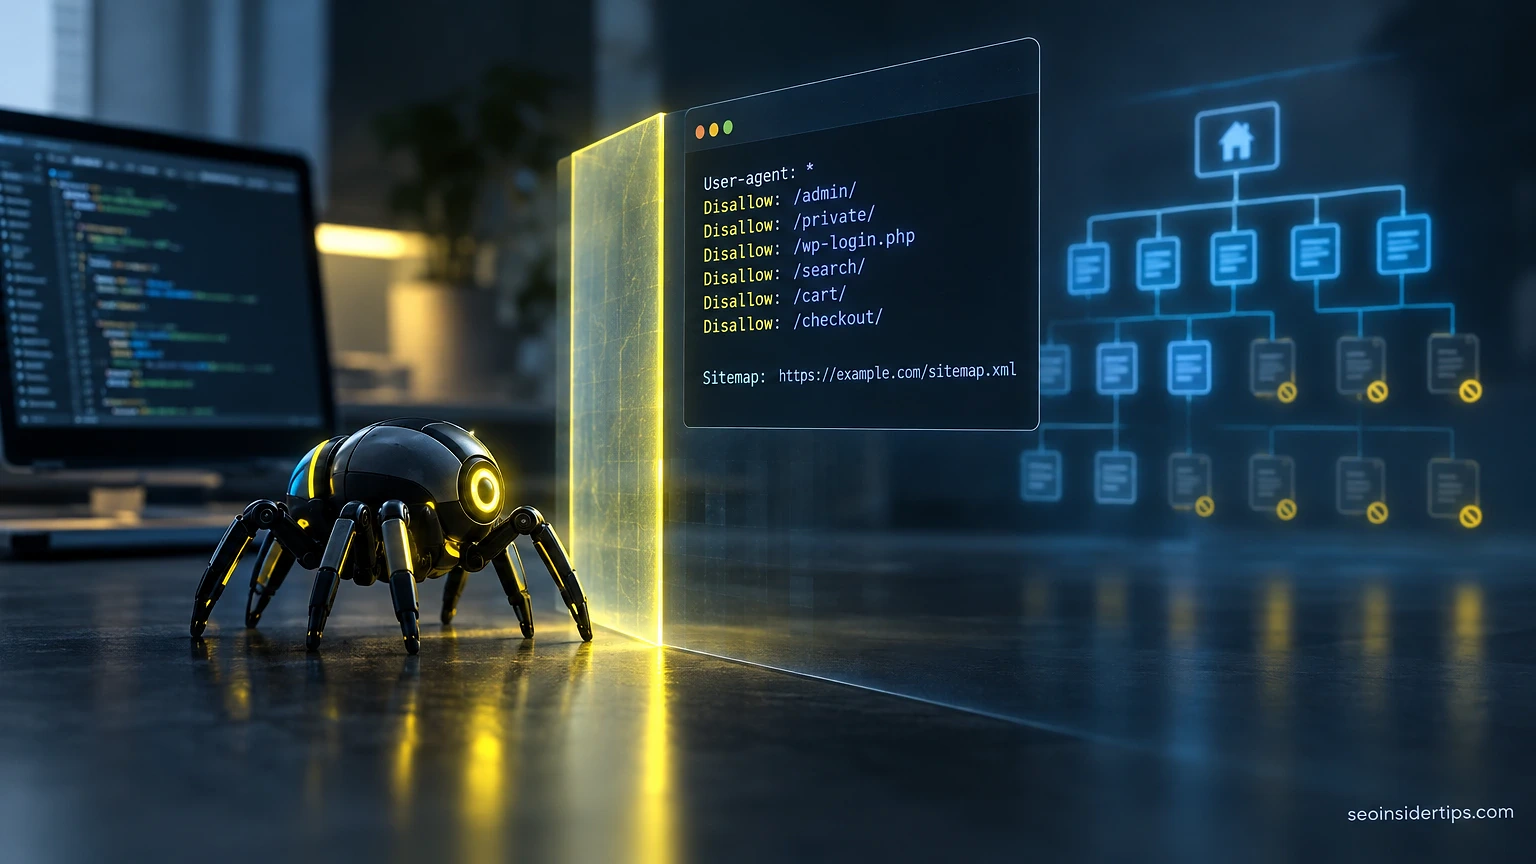
`robots.txt` sits at your root domain and tells compliant crawlers which paths to skip entirely. It’s a request, not a lock, since malicious bots ignore it freely. Meta robots tags, placed in the HTML `
`, offer page-level control with directives like `noindex, follow` or `noindex, nofollow`.⚠️ Warning: Never combine a `robots.txt` disallow with a `noindex` meta tag on the same URL. If the crawler can’t fetch the page, it never sees the noindex instruction, and the URL can still appear in search results as a bare link.
Canonical tags (``) tell Google which version of near-duplicate content to index. XML sitemaps, capped at 50,000 URLs per file under the sitemaps.org protocol, list priority pages for discovery.
Here’s the ranked list I walk through on every technical audit, in order of impact:
- Confirm `robots.txt` isn’t accidentally blocking CSS, JS, or entire subfolders.
- Check that canonical tags point to the correct self-referencing URL on indexable pages.
- Verify sitemap URLs return `200 OK`, not redirects or 404s.
- Audit meta robots tags across templates for conflicting noindex/index signals.
- Confirm `hreflang` tags match reciprocal pairs for multilingual sites, since mismatched tags confuse crawlers about which regional version to serve.
Getting these five right typically resolves 70-80% of the indexing complaints I see in support tickets.
JavaScript Rendering And Modern Crawl Challenges
Modern crawlers render JavaScript, but not instantly and not always fully. Googlebot uses a version of Chromium for rendering, evergreen and updated regularly, but the render step is queued separately from the initial fetch.
This creates a gap. A React or Vue site might get its HTML shell crawled in seconds, but the actual content, populated by client-side JavaScript, doesn’t get processed until the rendering queue catches up. On resource-strapped sites, that gap can stretch to several days.
Server-side rendering (SSR) or static site generation avoids this entirely by delivering fully-formed HTML on the first request. I moved a client off client-side-only rendering onto Next.js SSR last year, and their average time-to-index for new blog posts dropped from roughly 9 days to under 48 hours.
Dynamic rendering, where you serve pre-rendered HTML to bots and the full JS app to users, still works as a stopgap but Google generally recommends against it long-term in favor of proper SSR or hybrid rendering. Test your setup with the URL Inspection tool’s “View Crawled Page” feature. If critical content is missing from the rendered screenshot, crawlers are likely missing it too.
Putting It All Together For Better Crawlability
None of this works in isolation. A fast server with clean `robots.txt` rules still underperforms if your internal linking buries important pages five clicks deep. A perfect sitemap doesn’t help if half your URLs return soft 404s.
I tell every client the same thing: treat crawl efficiency as ongoing maintenance, not a one-time audit. Check Search Console’s crawl stats monthly. Pull server logs quarterly on anything over 10,000 pages. Fix redirect chains before they multiply.
The sites that rank consistently well aren’t always the ones with the most content. They’re the ones where search engine crawlers can move efficiently, find what matters, and index it without fighting through junk URLs or broken signals along the way.
Frequently asked questions
How often do search engine crawlers visit a website?
It varies by domain authority and update frequency. High-authority news sites can get crawled multiple times per hour, while a small static business site might see a Googlebot visit every few days. Check your Crawl Stats report in Search Console for actual numbers rather than guessing.
What’s the difference between crawling and indexing?
Crawling is the discovery and fetching of a URL. Indexing is the separate process of analyzing that content and storing it for potential search results. A page can be crawled repeatedly and still never get indexed if it’s thin, duplicate, or blocked by a noindex tag.
Can I block bad bots without blocking Googlebot?
Yes, using `robots.txt` user-agent rules or server-level firewall rules like those in Cloudflare. You can target specific user-agent strings to block scrapers while leaving Googlebot and Bingbot untouched.
Why is my new page not indexed after two weeks?
Usually it’s one of three things: thin content, a missing or incorrect canonical tag, or the page simply hasn’t been discovered yet because it’s orphaned with no internal links pointing to it. Submit it manually via URL Inspection and check back in 3-5 days.
Does crawl budget matter for small websites?
Rarely. Crawl budget becomes a real constraint mostly on sites with tens of thousands of pages or more. If you run a site under 1,000 pages with decent server response times, Google almost never struggles to crawl everything it needs.

Leave a Reply